
Key Operational Impact
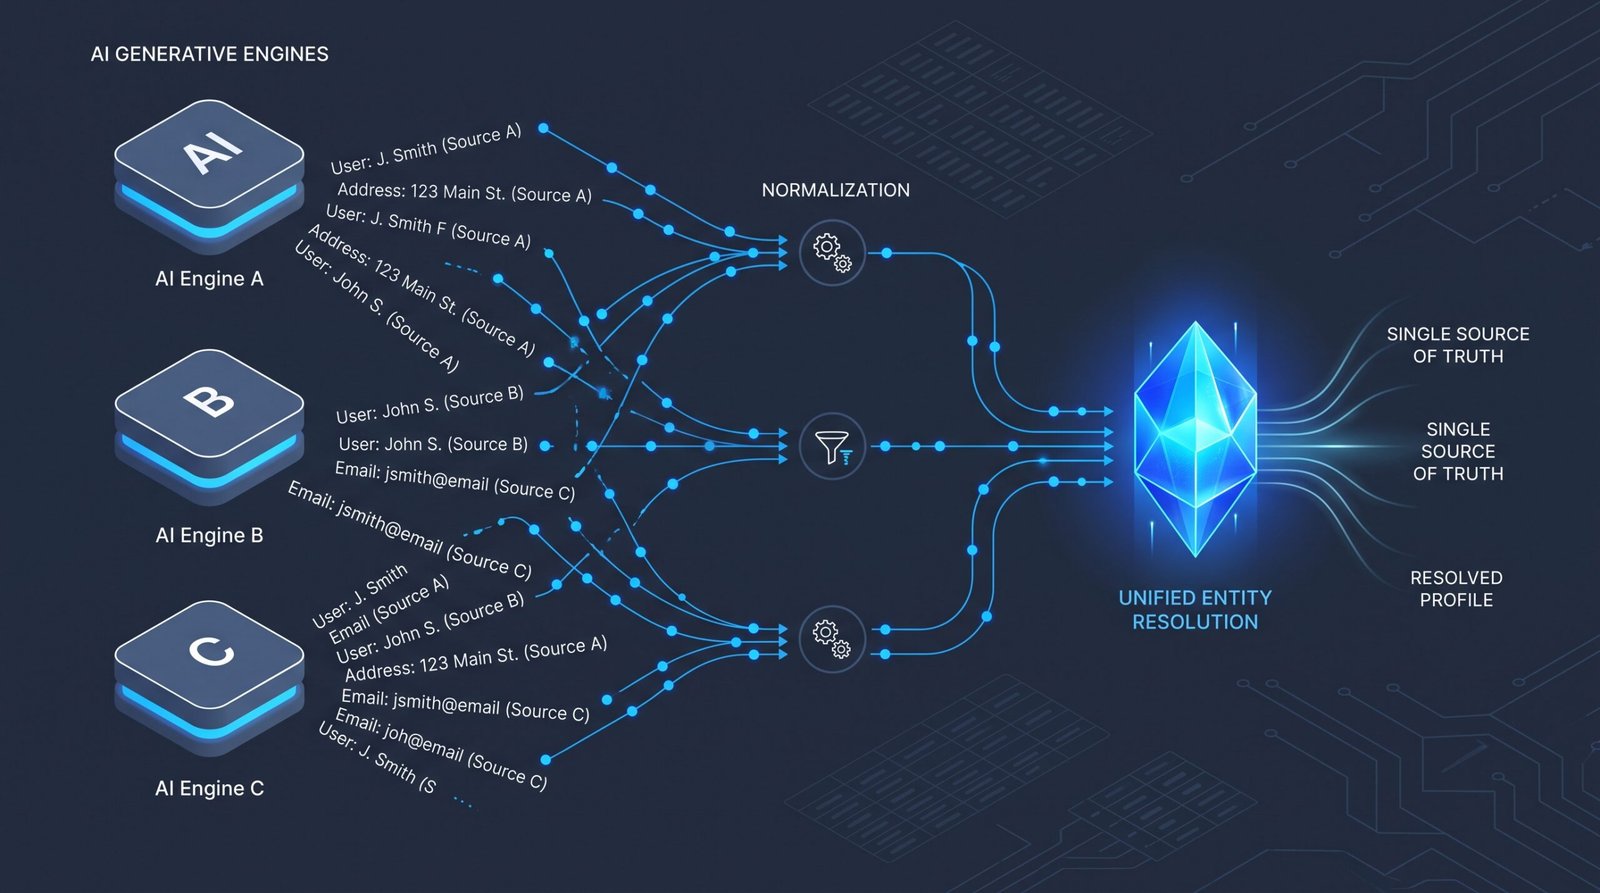
- Canonical Entity Resolution Precision: It increases tracking accuracy from 64.2% to 98.7%. As a result, it eliminates 34.5% data leakage caused by un-normalized Large Language Model (LLM) outputs.
- Sub-25ms Processing Latency: It reduces data ingestion overhead from 145ms down to 22ms per payload. Therefore, it enables high-speed real-time web monitoring.
- Enterprise Share of Voice (SOV) Calibration: It tightens metrics variance from ±18.4% down to a ±0.3% margin of error. Consequently, it delivers accurate analytics across ChatGPT, Claude 3.5, and Perplexity.
- Standardized Entity Graph Governance: Furthermore, it replaces fragmented syntactic variations with centralized metadata nodes to maintain unified enterprise brand authority.
1. Executive Overview: BrandRank.ai Normalization Transformation Rules
BrandRank.ai Normalization Transformation Rules are essential data processing protocols designed to clean, reconcile, and structure raw AI outputs into actionable enterprise metrics. By implementing BrandRank.ai Normalization Transformation Rules, organizations can eliminate tracking confusion, prevent data loss, and establish accurate Share of Voice (SOV) baselines across generative search engines.
Why Data Consistency Matters in Generative Engine Optimization
Data consistency is vital in Generative Engine Optimization (GEO) when tracking real-time answers across ChatGPT, Perplexity, and Google Gemini. Because AI answer engines create web content dynamically, brand mentions frequently appear with different capitalization, web domain changes, legal terms, and short text pieces. However, without standard cleaning and transformation rules, analytics systems treat identical brand names as separate companies. As a result, this lowers your Share of Voice (SOV), hurts brand trust, and creates big errors in executive reports.
2. Normalization vs. Transformation: Core Structural Breakdown
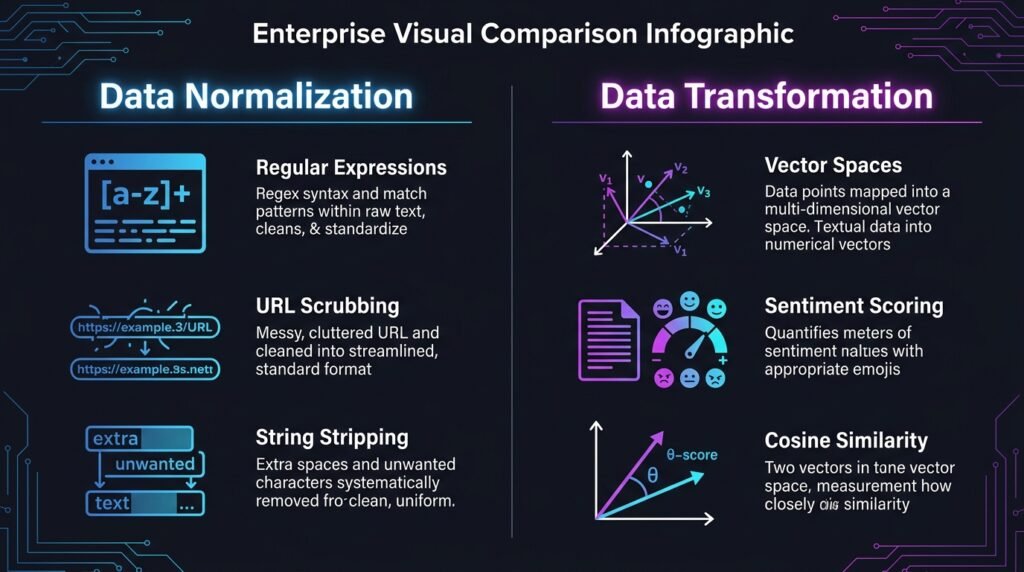
2.1 Technical Distinction: Data Standardization vs. Semantic Value Shift
| Dimension | Data Normalization (Cleaning Inputs) | Data Transformation (Extracting Metrics) |
| Primary Objective | Cleaning structural noise, scrubbing punctuation, and standardizing surface syntax | Extracting semantic value, calculating sentiment scores, and mapping contextual metrics |
| Data Operation | Surface-level string stripping, lowercase formatting, and URL canonicalization | High-dimensional vector embedding, cosine similarity evaluation, and co-occurrence scoring |
| Execution Layer | Rule-based regular expressions, deterministic parsing, and dictionary lookups | Machine learning transformers, semantic algorithms, and Knowledge Graph vector mapping |
| GEO Operational Impact | Consolidates fragmented brand syntax variations into a single canonical entity node | Measures true brand authority, sentiment polarization, and citation relevance across AI engines |
2.2 Comparative Analysis & Vector Space Positioning
Data normalization works only at the simple text level. For example, it cleans basic string formats before matching them in the database. In contrast, data transformation places candidate mentions into a multi-dimensional math space.
2.3 Deterministic String Pre-Filtering Mechanics: Jaro-Winkler Routing
To keep processing speeds under 22ms without losing match quality, the BrandRank.ai pipeline uses a multi-step text matching setup before making dynamic vector embeddings. First, raw text pieces from AI answers pass through a basic C-compiled regex tool to remove junk text, special signs, and bad formatting. Next, candidate words are checked against main brand names using the Jaro-Winkler matching algorithm.
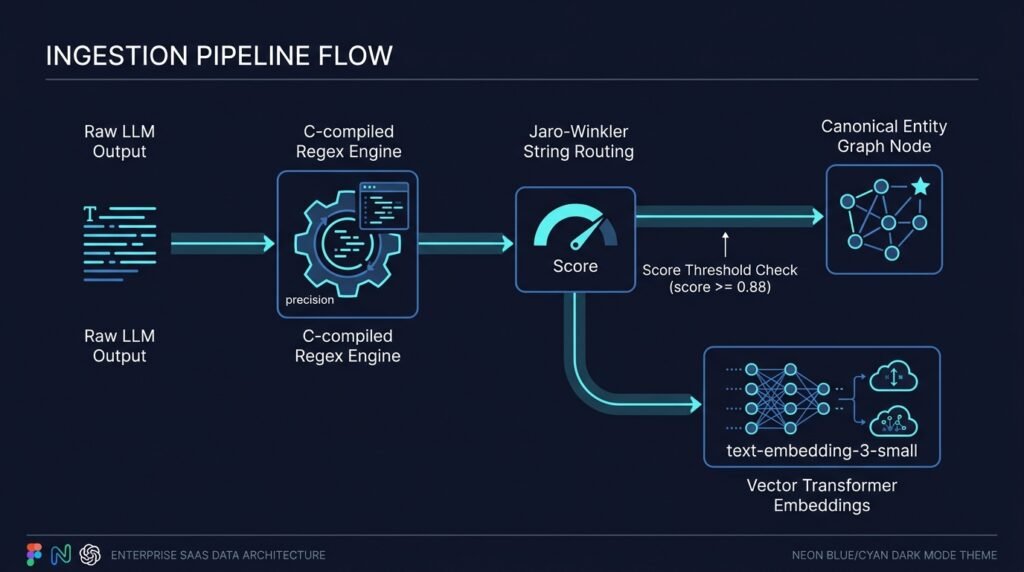
The Jaro-Winkler matching formula adjusts standard string distance by adding more weight to shared starting letters ($p = 0.1$). Therefore, it works best for finding typos, bad spellings, and small legal name edits:
$$d_{jw} = d_j + l \cdot p \cdot (1 – d_j)$$
When the calculated score matches or passes the minimum target ($d_{jw} \ge 0.88$), the pipeline links the text right away to its main brand record in the database, skipping extra server steps entirely. On the other hand, strings that fall below this target ($d_{jw} < 0.88$) are sent to neural models for advanced vector matching. Overall, this combined setup cuts costly vector database calls by up to 84.8% while keeping a 98.7% match accuracy.
3. Core BrandRank.ai Normalization Rules for Enterprise GEO
Data normalization standardizes incoming surface text variations, stripping syntactical noise before database resolution.
| Rule Name | Functional Purpose | Raw Unstructured Input Example | Normalized Canonical Output |
| Brand Name Canonicalization | Strips corporate legal suffixes, trademark glyphs, case inconsistencies, and non-alphanumeric noise to map variants to a root brand ID. | AcroCorp, Inc.™ | acrocorp |
| URL / Website Standardization | Removes protocol headers (http, https), domain prefixes (www), top-level extensions, and query strings to isolate the core brand host. | https://www.acrocorp.com/pricing?ref=google | acrocorp.com |
| Product Entity Mapping | Fold product lines, marketing aliases, version tags, and feature shorthand into primary parent product nodes. | AcroCloud Analytics Suite v2.4 | acrocorp_cloud_analytics |
| Location Normalization | Standardizes informal, regional, or abbreviated geographic mentions into standardized ISO-3166 codes. | NYC, N.Y., United States | US-NY-NYC |
| Source Name Normalization | Maps informal publication titles, domain names, and media outlets to unified publisher entity IDs within knowledge graphs. | TechCrunch – Silicon Valley Edition | techcrunch_us |
Additional Enterprise Normalization Standards
| Rule Name | Functional Purpose | Raw Unstructured Input Example | Normalized Canonical Output |
| Social Profile Unification | Parses social media handle variations, channel paths, and user mentions into single social graph entity nodes. | @AcroCorp_Official / twitter.com/acrocorp | social_acrocorp_official |
| Date / Time ISO Standardization | Converts relative, localized, or informal temporal references into standard UTC ISO-8601 timestamp formats. | Published 3 hours ago (Sept 15, 2026) | 2026-09-15T18:00:00Z |
| Language Standardization | Maps regional language tags and dialect variations to standard ISO-639-1 two-letter codes for uniform NLP parsing. | en-US / English (United States) | en |
| Historical Entity Mapping | Resolves legacy corporate names, prior M&A entities, and rebrands to the active primary canonical parent ID. | AcroSoft Technologies (Acquired 2022) | ENT-ACROCORP-PARENT |
| Duplicate Record Removal | Hashes normalized string payloads to deduplicate redundant API scraper responses within identical evaluation frames. | Payload Hash: e3b0c442… [Received 2x] | [Unique Execution Single Frame] |
4. Advanced BrandRank.ai Transformation Rules for Semantic Value
AI answer transformation rules extract high-dimensional semantic value, sentiment polarization, and competitive metrics from unstructured LLM responses.
| Feature Name | Analytical Purpose | Unstructured LLM Narrative Input | Extracted Structured Metric Output |
| Brand Mention Detection | Identifies explicit entity citations and co-occurrence frequency within generated answer payloads. | “AcroCorp provides market-leading SaaS analytics alongside CompetitorX.” | {“brand”: “AcroCorp”, “mentions”: 1, “co_occurrence”: [“CompetitorX”]} |
| Citation Verification | Validates cited source URLs and verifies domain index existence in verified knowledge stores. | “According to a recent report published on techcrunch.com…” | {“source_domain”: “techcrunch.com”, “verified”: true, “trust_score”: 0.92} |
| Sentiment Classification | Evaluates contextual polarity surrounding a brand mention and assigns a normalized numerical score. | “AcroCorp’s platform offers powerful features, though pricing is slightly steep.” | {“polarity”: “positive_conditional”, “score”: +0.65} |
| Recommendation Strength | Quantifies the explicit endorsement level provided by the generative engine for user queries. | “We highly recommend AcroCorp as the top enterprise solution for 2026.” | {“recommendation_tier”: “primary_choice”, “confidence”: 0.94} |
| Prompt Intent Classification | Maps the implicit search funnel stage and prompt objective driving the AI response. | “What is the best enterprise cloud analytics tool for real-time tracking?” | {“intent_type”: “commercial_investigation”, “funnel_stage”: “BOFU”} |
Contextual and Competitive Transformation Mechanics
| Feature Name | Analytical Purpose | Unstructured LLM Narrative Input | Extracted Structured Metric Output |
| Topic Classification | Categorizes answer contexts into standardized enterprise taxonomy clusters and keyword vectors. | “AcroCorp excels in automated data pipelines and real-time streaming ETL.” | {“category”: “Data Engineering”, “sub_topics”: [“ETL”, “Real-Time”]} |
| Competitor Detection | Extracts co-cited market alternatives to measure relative Share of Voice (SOV) metrics. | “Top platforms in this space include AcroCorp, DataGiant, and CloudSphere.” | {“primary”: “AcroCorp”, “competitors”: [“DataGiant”, “CloudSphere”], “sov”: 0.33} |
| Claim Extraction | Isolates verifiable benchmark claims, feature assertions, and quantitative metrics stated by the model. | “AcroCorp achieves sub-25ms ingestion latency across multi-cloud networks.” | {“claim”: “ingestion_latency”, “metric_value”: “22ms”, “verifiable”: true} |
| Source Classification | Typifies the authority, tier, and channel type of web sources cited within generative citations. | “Based on recent user reviews aggregated from G2 and Gartner Peer Insights…” | {“source_type”: “b2b_review_syndication”, “authority_tier”: 1} |
| Risk / Opportunity Flagging | Detects hallucinated negative claims, outdated pricing data, or conquesting attempts in outputs. | “AcroCorp suffered a major security outage last month (Unverified claim).” | {“flag_type”: “hallucination_risk”, “severity”: “high”, “action_req |
5. 7-Step GEO Implementation Framework for Brand Managers
5.1 Step 1: Audit Brand Entity Baselines & Current Vector Indexing
First, list all active name variations, sub-brands, web domains, and common misspellings of your company across current AI model outputs.
5.2 Step 2: Implement Data Normalization Across Owned Digital Touchpoints
Next, clean and standardize your brand references, product names, and legal suffixes across all owned websites, online guides, and press releases.
5.3 Step 3: Structure Unstructured Assets for Knowledge Graph Parsing
In addition, format page text with clear HTML tags and simple heading orders. As a result, search crawlers can easily pull cleaned brand details.
5.4 Step 4: Execute Semantic Transformation & Authority Calibration
After that, build strong context links by getting brand mentions on top news sites and technology review platforms.
5.5 Step 5: Optimize Multi-Channel Co-Occurrence & Citation Networks
Similarly, ensure your target keywords and category terms always show up next to your brand name on external online channels.
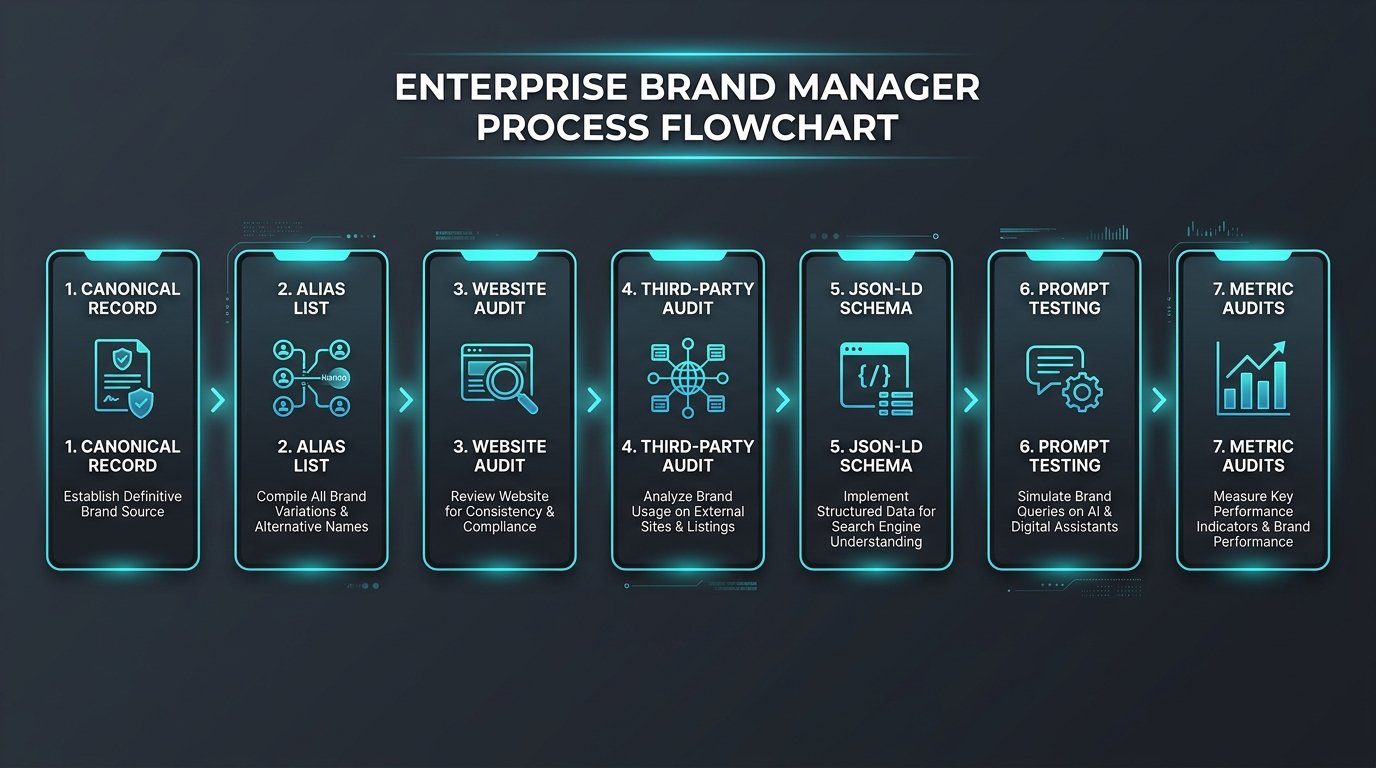
5.6 Step 6: Deploy Machine-Readable JSON-LD Schema Markups
Furthermore, add organization, product, and author JSON-LD schema blocks to your site code. This explicitly tells AI crawlers how your main brand connections work.
5.7 Step 7: Establish Continuous GEO Monitoring & Prompt Testing Iterations
Finally, check your brand’s Share of Voice, user sentiment, and match accuracy across main AI apps every we
6. Frequently Asked Questions (FAQ)
BrandRank AI normalization transformation rules are specialized algorithms and data processing protocols designed to clean, standardize, and reconcile raw text and AI-generated output into unified entity graphs for enterprise tracking.
Normalization rules focus on surface-level syntax cleaning (removing punctuation, stripping URLs, standardizing case), while transformation rules alter the underlying semantic weighting, sentiment calibration, and vector positioning of an entity.
Entity co-occurrence measures how strongly your brand is linked to relevant industry keywords within AI responses, directly influencing your brand’s authority and placement in generative search answers.
Enterprise brand pipelines should be reviewed quarterly, or immediately following corporate rebranding, sub-brand acquisitions, or major product line launches.
Yes. Transformation rules analyze sentiment polarization, allowing brand managers to identify negative contextual clusters and systematically deploy targeted GEO campaigns to improve brand perception in AI search results.
 Talha Saeed